A Decision Graph for Small AI Teams: Context That Compounds
Small teams don't lack notes. They lack the links between evidence, decisions, work and outcomes. A practical decision graph model, a copyable record and the test that shows whether yours works.
Share
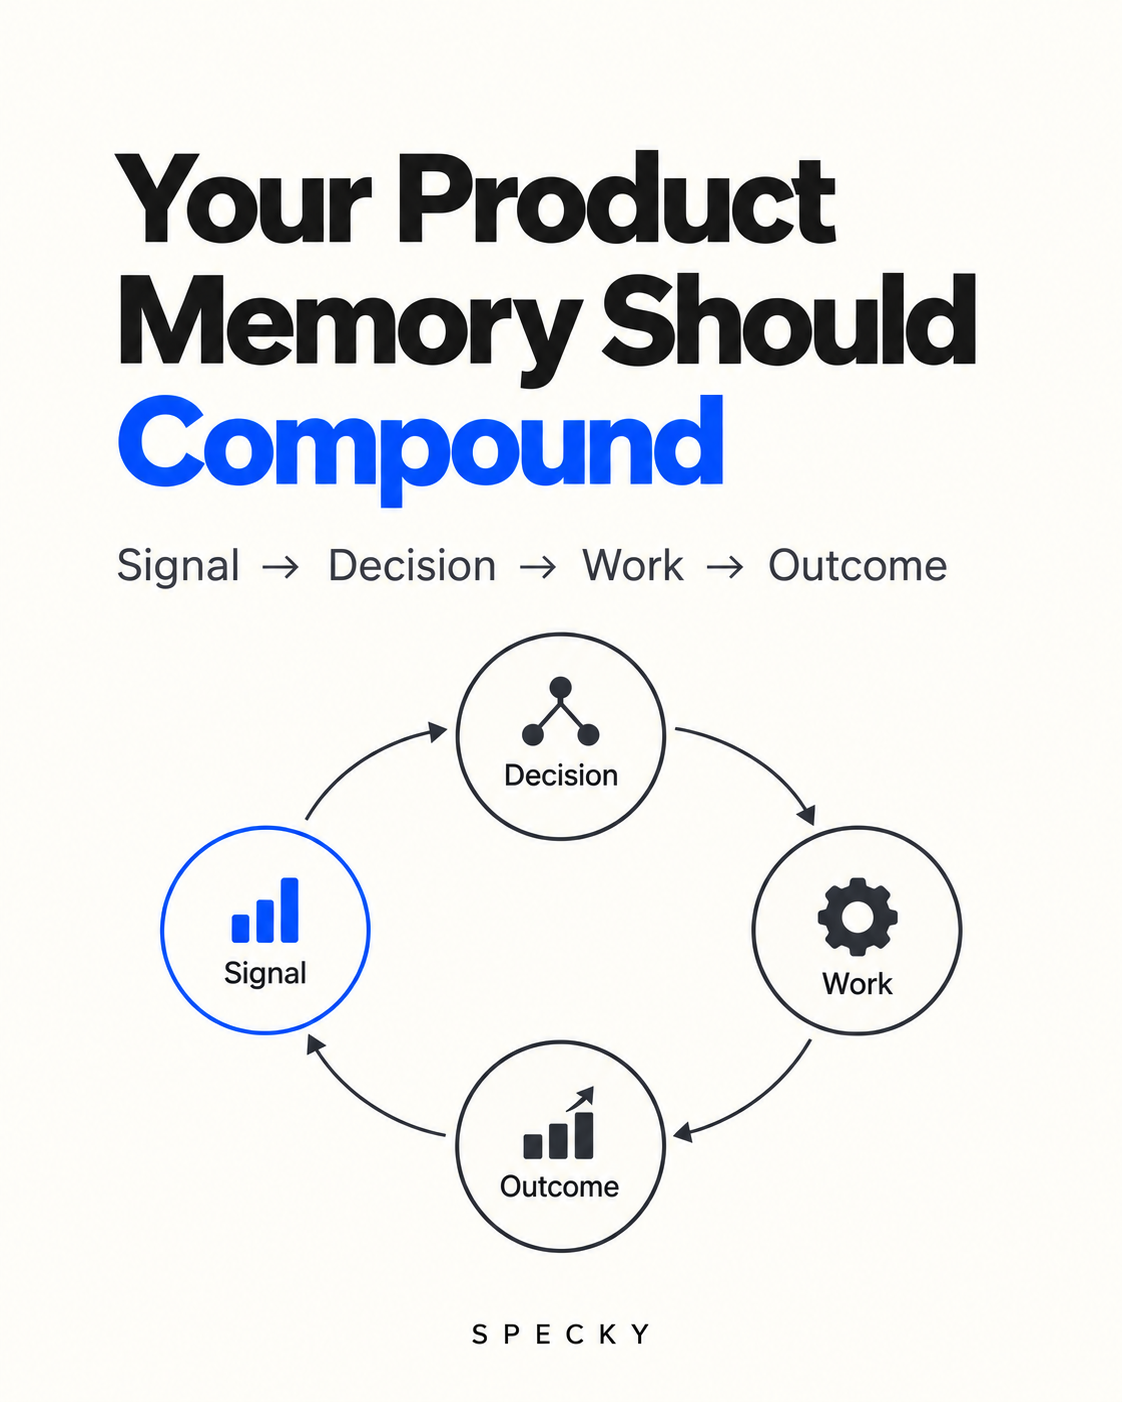
A decision graph is a record that links four things: the signal that changed what a team believed, the decision it made, the work that decision produced, and the outcome that came back. Small AI-native teams need one because their context lives in two or three heads. Without the links, "why did we build this?" gets answered from memory, or not at all.
Key takeaways
Teams spend over 25% of their workweek searching for information, according to Atlassian's State of Teams 2025 (Atlassian, 2025). Missing decision context is a big share of that search.
Median job tenure in the US was 4.1 years in January 2026, and 3.0 years for workers aged 25 to 34 (BLS, 2026). On a small team, the person who knows why will leave sooner than you think.
Engineers solved half of this problem in 2011: Michael Nygard's architecture decision record has five fields and exists to stop "blind acceptance or blind reversal" of old choices (Nygard, 2011).
A decision log lists choices. A graph connects them to evidence before and outcomes after. The connections are what let the team learn.
One test tells you if yours works: can a new teammate go from a customer signal to the decision, the work and the result without asking anyone?
Why do small teams lose their product context?
Small product teams rarely lack information. They have information that can't be used twice.
A customer interview happens. A founder makes a decision. An engineer ships a change. A metric moves, or doesn't. Three months later the team remembers fragments of the story but not the chain that connected the signal to the decision. The expensive version of what people call "product memory" is a pile of accurate notes that still leaves the team asking why.
Three things make this worse on small AI-native teams:
Context is carried by one or two people. That feels efficient until someone joins, a priority changes, or the original decision maker can't remember the reasoning six months later.
People move on. With median tenure at 3.0 years for 25-to-34-year-olds (BLS, 2026), a five-person team should expect regular departures. As rough arithmetic, not a forecast: if each person stays about three years, a team of five loses someone every seven months or so.
AI speeds up output, not reasoning capture. A coding agent can produce a feature in an afternoon. It doesn't record why the feature was worth building, and it will happily rebuild something the team decided against last quarter if nobody wrote that down.
What is the difference between stored knowledge and usable context?
A document tells you what someone wrote down. Usable context tells you what the team believed, what evidence shaped that belief, what changed afterwards and what is still uncertain.
A document is usually organised around an event: an interview summary, a PRD, a roadmap update, a launch note, a status report. A decision is organised around a question:
Which customer problem should we solve first?
What are we assuming?
What would make this bet wrong?
What work follows if we commit?
When will we know whether it worked?
The first structure is good for retrieval. The second is good for judgement. A folder of well-written documents can still fail the team, because the relationships between them were never recorded.
Decision log vs decision graph vs wiki
Wiki or doc folder
Decision log
Decision graph
Unit
Document
Decision entry
Linked records: signal, decision, work, outcome
Answers
"Where is the spec?"
"What did we decide, and when?"
"Why did we decide it, what did it produce, did it work?"
What does a decision graph look like? Signal → Decision → Work → Outcome
A practical version is built around four connected objects.
1. Signal
A signal is something that might change what you do: a repeated customer request, a support pattern, an interview observation, a usage change, a sales objection, a technical constraint. A signal is not automatically a requirement. It is evidence that deserves interpretation.
Useful fields:
What happened?
Where did it come from (with a link to the source)?
Who or what does it represent?
How often has it appeared?
What does it suggest?
What does it not prove?
The last question matters. A single loud request can be real without being representative. Our breakdown of what counts as evidence for each product risk shows which signals carry weight for which question.
2. Decision
A decision records the commitment the team made in response to the signal. A durable decision has five parts:
The question being answered.
The choice made.
The alternatives considered.
The evidence and assumptions behind it.
The condition that would cause the team to revisit it.
The fifth field turns a log into a learning system. Without it, the log is an archive of opinions. With it, the team can tell whether a decision was wrong, premature, or right for the information it had at the time.
This mirrors the architecture decision record Nygard proposed in 2011, with Title, Context, Decision, Status and Consequences (Nygard, 2011). His argument applies to product choices too: a newcomer facing an unexplained decision can only accept it blindly or reverse it blindly, and both are risky.
3. Work
Work is the concrete expression of the decision: a spec, experiment, ticket, prototype, workflow or customer conversation.
Linking work to decisions prevents a common failure. Teams have a thoughtful strategy conversation and then produce work with no visible relationship to it. When decision and work are connected, you can check whether the implementation actually tests the belief it was supposed to test.
4. Outcome
An outcome is what happened after the work reached users or the team. It doesn't need to be a perfect metric. It can be a measured change, a customer response, a failed experiment, a delayed result or an explicit "we don't know yet".
What matters is that the result returns to the original decision. Otherwise every launch starts a new story and the team loses the chance to improve its judgement.
How does this relate to an opportunity solution tree?
Teresa Torres's opportunity solution tree, introduced in 2016, maps an outcome to opportunities, solutions and assumption tests (Product Talk, 2023). The tree is the plan for discovery. The graph is the record of what you chose along the way and what happened next. They fit together: each solution you commit to becomes a decision node, and each assumption test becomes work with an outcome attached.
How do you know it works? The new-teammate test
You can test whether your product context is usable with one question:
Can a new teammate move from an observed signal to the resulting decision, the work it created, and the evidence that came back, without asking anyone?
If the answer is no, the problem isn't search. The connections were never made.
A useful one lets you move in both directions:
From a customer signal to the decisions it influenced.
From a decision back to the evidence that justified it.
From a decision to the specs, experiments and tickets it created.
From an outcome back to the original assumption.
From a strategy statement to the current work that supposedly supports it.
That is why a graph beats a folder of summaries. Each item being available is not the value. The visible relationship between items is. For the data model behind this, see our explainer on knowledge graphs for product management.
Which decisions deserve a full record?
Not every choice needs five fields. Jeff Bezos's 2016 shareholder letter separates reversible "two-way door" decisions, which can use a lightweight process, from the rest. He also argued that most decisions should be made with about 70% of the information you wish you had (Amazon, 2017).
A workable rule for a small team:
Full record for decisions that are expensive to reverse: pricing, data model, a new customer segment, killing a feature, anything that takes more than two weeks of build.
One line for two-way doors: copy tweaks, small UX changes, internal tooling. Note the choice and the signal, skip the rest.
Always record the revisit condition when you decide with incomplete information. If you're deciding at 70% confidence, write down what the missing 30% would need to show to change your mind.
Copyable decision record template
Paste this into whatever tool you use. Each line in brackets should be a link, not a paraphrase.
Decision: [one sentence, specific enough to be wrong]
Question it answers: [the product question]
Owner (approver): [one name]
Contributors: [names]
Date decided:
Signals: [links to interviews, tickets, events]
What the signals don't prove: [one line]
Alternatives considered: [2-3 options and why not]
Assumptions: [the beliefs that must hold]
Confidence: [e.g. 60%]
Work created: [links to spec, tickets, experiment]
Expected outcome: [metric or behaviour, and by when]
Revisit if: [condition that reopens the decision]
Outcome observed: [filled in later, with link]
The owner line follows Atlassian's DACI play, which insists on one approver among the Driver, Approver, Contributors and Informed roles; it is designed for 3 to 6 people and runs in about 60 minutes (Atlassian). A single named approver makes it obvious who to ask when the revisit condition fires.
How do you run the workflow in practice?
Start with one real product question, not a migration project.
Worked example (illustrative). A four-person AI startup asks: "Should we invest in reducing the time from a customer signal to a usable product decision?"
Collect the evidence. Pull together the 6 interview notes, 14 support messages and the usage trend that bear on the question. Keep each source linked. A synthesised statement is more trustworthy when the team can open what it came from.
Record the decision with a confidence level. "Build a weekly evidence digest for the founder, 65% confident it cuts decision time." Confidence is a forecast to compare against later, not a performance of certainty.
Connect it to one small piece of work. A two-week prototype, sent to 5 design partners. The work should make the decision more testable, not just keep the team busy.
Define the return path before shipping. "If median time from signal to decision doesn't drop from 12 days to under 7 within 6 weeks, revisit." Put the check date on the calendar.
Close the loop. Six weeks later, record what happened and link it to the decision, even if the answer is "unclear". Over a quarter, compare stated confidence with how often bets paid off. That comparison is how the team's judgement improves.
The useful output is not a prettier summary. It is a shorter path from evidence to responsible action.
What changes for a small team?
New teammates understand not only what is being built, but why it exists.
Founders stop answering the same context question from recall.
PMs spend less time reconstructing status and more time testing whether the product is moving towards the intended outcome.
Engineers and coding agents see the decision behind a request instead of an isolated task. That matters more as more tickets go straight to an agent; see our guide to giving AI coding agents product context.
Wrong decisions become lessons, not blame. A good record doesn't protect the decision. It protects the reasoning process by making the assumptions visible.
Common mistakes
Recording decisions without signals. A log of conclusions with no evidence links is an opinion archive.
Skipping the revisit condition. Without it, nobody knows when a decision has expired.
Treating AI summaries as sources. A generated theme is a pointer to evidence, not evidence. Keep the raw links.
Writing records after the fact. Reconstructed reasoning is flattering reasoning. Write the record when you decide.
Recording every two-way door. If the template feels like bureaucracy, people stop using it. Save the full record for expensive choices.
Never filling in the outcome. A graph with empty outcome fields is a decision log with extra steps.
Where Specky fits
In Specky, this is the loop the product is built around: signals from calls, feedback, Slack, Jira and analytics land in the Product Graph with their sources; the Decision Log records the choice and cites the evidence behind it; specs and tickets carry inline citations; and after launch you can check whether the bet worked. Your team still makes the decision. The links get made as you work instead of being reconstructed later.
Frequently asked questions
What is a decision graph in product management?
It is a connected record of product choices. Each decision links back to the signals that informed it (interviews, tickets, usage data) and forward to the work it created and the outcome measured afterwards. Unlike a flat decision log, it lets anyone trace a shipped feature to its evidence, or a customer complaint to every decision it influenced.
How is a decision graph different from a decision log?
A decision log is a list of entries: what was decided, by whom, when. A graph adds links on both sides of each entry, to the evidence before it and to the work and outcome after it. The log tells you what happened. The graph tells you whether the reasoning held up, which is what makes later decisions better.
What is product memory?
Product memory is an informal name for a team's accumulated knowledge of why its product is the way it is: the customer evidence, decisions, trade-offs and results behind each feature. Notes and documents store pieces of it. It only becomes usable when those pieces are linked, so someone new can follow the reasoning without asking the people who were there.
How much time does linking decisions take?
Less than people fear. A full record is a short page of writing when the evidence is already linked, and most two-way-door choices need a single line. The bigger cost is the habit of linking work and outcomes back to decisions. Teams that skip it pay later, in the over 25% of the workweek Atlassian found people spend searching for information.
Do small teams really need this?
Small teams need it most, because context is concentrated in very few people. With median tenure around 3 years for younger workers, the person who knows why a decision was made will often be gone within a few product cycles. One page of linked decisions is cheaper than re-litigating old choices every time someone new joins.
GDPR-aligned. EU workspace data is stored in Frankfurt, Germany. GDPR and EU data Built in Vienna, Austria. A product of influence solutions fm GmbH (FN 675374y). Imprint 14-day trial. Card required, and nothing is charged until day 14. 30-day refund after subscribing. See pricing